Faster releases
GitOps with ArgoCD and health gated progressive rollouts made deployments 10× faster and saved 100+ hours of manual work.
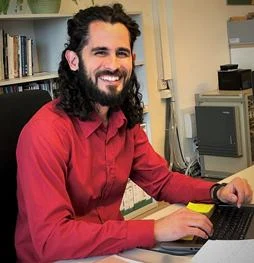
Fribourg, Switzerland · B permit · Open to remote roles
Nearly 5 years running production across 300+ clusters on AWS, Azure, GCP and Linode. I turn manual operations into automated, self healing platforms.
CKA certified · 10× faster deployments · 27% lower AWS cost
I engineer toil out of existence, so your fleet ships faster, costs less to run and stays calm when it matters.
GitOps with ArgoCD and health gated progressive rollouts made deployments 10× faster and saved 100+ hours of manual work.
Cut AWS platform cost by 27% and EKS extended support cost by 82.5% with autoscaling, right sizing and a planned 1.24 to 1.29 upgrade.
Automated OOM remediation removed 20+ hours of toil and 20 to 30 incidents every month.
Owned EMEA on call and incident command through peak traffic events such as Black Friday and the Super Bowl.
Thirty minutes on your stack, your pain points and the role. No slides, no pressure.
I walk your engineers through real case studies, with the numbers, the trade offs and what I would change.
I bring a written plan covering reliability, cost and delivery, based on what I learned from you.
Four projects, each with the problem, what I did and what changed.
10×
faster deployments
Hydrolix · 2024 to present
Fleet scale
health gated rollouts
Hydrolix · 2024 to present
20 to 30
incidents a month eliminated
Hydrolix · 2024 to present
27%
lower AWS platform cost
Triggle Spain · 2023 to 2024
Recommendations from people I worked with, as written on LinkedIn.
I had the pleasure of managing Yaiser for around 18 months as part of our SRE team. During that time, he helped maintain the reliability of our multi-cloud Kubernetes estate, which grew to several hundred clusters across four cloud providers. He contributed significantly to our move towards GitOps and ArgoCD... Above all, Yaiser was always reliable, willing to go the extra mile when needed, and genuinely a great guy to work with.
Jason Turner
Technology leader, Hydrolix
Managed Yaiser directly · September 2026
He has a strong understanding of site reliability engineering and takes a thoughtful, practical approach to keeping the systems running, improving automation and solving issues. Yaiser is someone you can count on especially when things get challenging.
Kelvin Wee
Global Services Director, Hydrolix
Senior to Yaiser · October 2026
Yaiser stays calm under pressure, which makes him someone people naturally lean on when things get difficult. He's genuinely curious and digs into problems until he truly understands them, so his decisions are thoughtful and well reasoned. He communicates clearly and without ego.
Tameem Akhtar
Site Reliability, Hydrolix
Worked with Yaiser on the same team · October 2026
He's one of the best SREs I've come across. He's the guy you want around when things break: calm, sharp, and always focused on fixing the problem. He also made our systems quieter and more reliable, and explained things in a way everyone could follow.
Guillermo Vignau
Solutions Architect, Hydrolix
Worked with Yaiser on the same team · October 2026
What makes Yaiser truly valuable is his consistency. Regardless of the environment or the circumstances, he brings the same reliable, team first energy. Any SRE or infrastructure team would benefit greatly from having him on board.
Nelson Jaime Galván
DevOps and SRE, Hydrolix
Worked with Yaiser at Accenture and Hydrolix · May 2026
Yaiser has strong hands on experience with Kubernetes and distributed systems... One of his key strengths is observability. During incidents, Yaiser stays calm and focused, quickly works through complex problems, identifies root causes, and drives issues to resolution while maintaining clear communication with the team.
Jose Augusto Schiavoni
DevOps Engineer, Platform Engineering, Hydrolix
Worked with Yaiser on the same team · October 2026
Yaiser demonstrated impressive technical expertise, effectively maintaining both on premises and AWS cloud services. His ability to automate deployments and ensure system scalability was crucial to the success of our projects. He was also a great support to junior profiles.
Alex Curiman
Tech Lead, Epam Neoris
Managed Yaiser directly at atSistemas · August 2024
He is one of the most skilled DevOps Engineers I have ever worked with. Yaiser excels not only in technical expertise but also in leadership and collaboration. He is also a fast learner, and found a way to educate himself with new technologies that were needed to specific projects.
Jose Antonio Alvarez González
Java Software Developer, Triggle
Worked with Yaiser on the same team · September 2024
What I build and run for myself, with the same habits I use at work: monitoring from outside, least privilege and infrastructure I can rebuild.
Running daily
Drive a coding agent from a Discord thread
A TypeScript bot that opens a thread per task and streams Claude Code's work back while it runs on my machine. It runs as a launchd agent under my own user, limits its reach to one workspace with a Seatbelt sandbox, and replaced an earlier design that ran as root and buffered output.
Running daily
A watcher that can notice when the machine dies
A host cannot report its own death, so the alarm lives elsewhere. A reporter on the Mac edits one pinned Discord message every 5 minutes and posts a beat to a Cloudflare Worker. A cron in the Worker checks the last beat in KV and alerts through a webhook, then posts a recovery line.
Built in 2024
Personal brand automation on the edge
A small CRUD interface for post drafts and a Cloudflare Worker that reads them from a Turso SQLite database and publishes through the LinkedIn API at planned times.
Private demo on request
Learn French by listening, with no data leaving my Mac
You paste a French text and a neural voice (Kokoro) reads it sentence by sentence. A local model (Ministral 3 8B on Ollama) prepares the lesson: translation, vocabulary in context, comprehension questions and a chat tutor. In dictation mode the diff is computed in code and the model only explains the differences. It runs on an Apple M3 Pro with 18 GB of memory, as a small Node server with no npm dependencies, published through a Cloudflare Tunnel behind Cloudflare Access.
Jul 2024 to present
Remote, Switzerland · via Oyster HR
Petabyte scale streaming analytics platform. Multi cloud Kubernetes fleet of 300+ clusters and 20,000+ pods.
Jul 2023 to Jul 2024
Spain
Tourism PaaS on AWS and Azure. Led a DevOps team of 3.
Feb 2023 to Jul 2023
Spain
Airline customer, on premise and AWS services.
Feb 2022 to Feb 2023
Spain
Banking customer.
The Linux Foundation, 2026
AWS Certified Cloud Practitioner
Amazon Web Services
Claude Code 101 and AI Fluency
Anthropic Academy, 2026
Education: Master in Software Development (Assembler Institute), MSc Plant Breeding, MSc Plant Biology, BSc Biological Sciences.
I live in Fribourg and hold a valid B permit, so no sponsorship is needed.
Yes. I have worked fully remote on a global team since 2024 and I am on Central European time.
Full time first. I will consider contracts when the scope is clear and the work is substantial.
Kubernetes with ArgoCD and GitOps, Pulumi and Terraform, Go for tooling, and Prometheus with Grafana for observability.
More than 300 production clusters and 20,000 pods across AWS, Azure, GCP and Linode.
Certified Kubernetes Administrator (2026) and AWS Certified Cloud Practitioner, plus Anthropic Academy training on AI tooling.
Spanish is my native language, my English is fluent (C1) and used daily at work, and my French is A2 to B1 with courses under way, aiming for B1.
Notice period to be confirmed. Book a call and I will give you an exact date.
Thirty minutes, no preparation needed. I am based in Switzerland, hold a B permit and work remotely.
Prefer email? [email protected]